The architecture assumption that defined mobile development for most of the past decade was straightforward: the device handles the interface, the server handles the intelligence. Recommendations, search, content ranking, moderation, personalization, and anything requiring a model ran in the cloud. The app was a display layer and an input collector.
That assumption is breaking down, and iOS is where the shift is most visible.
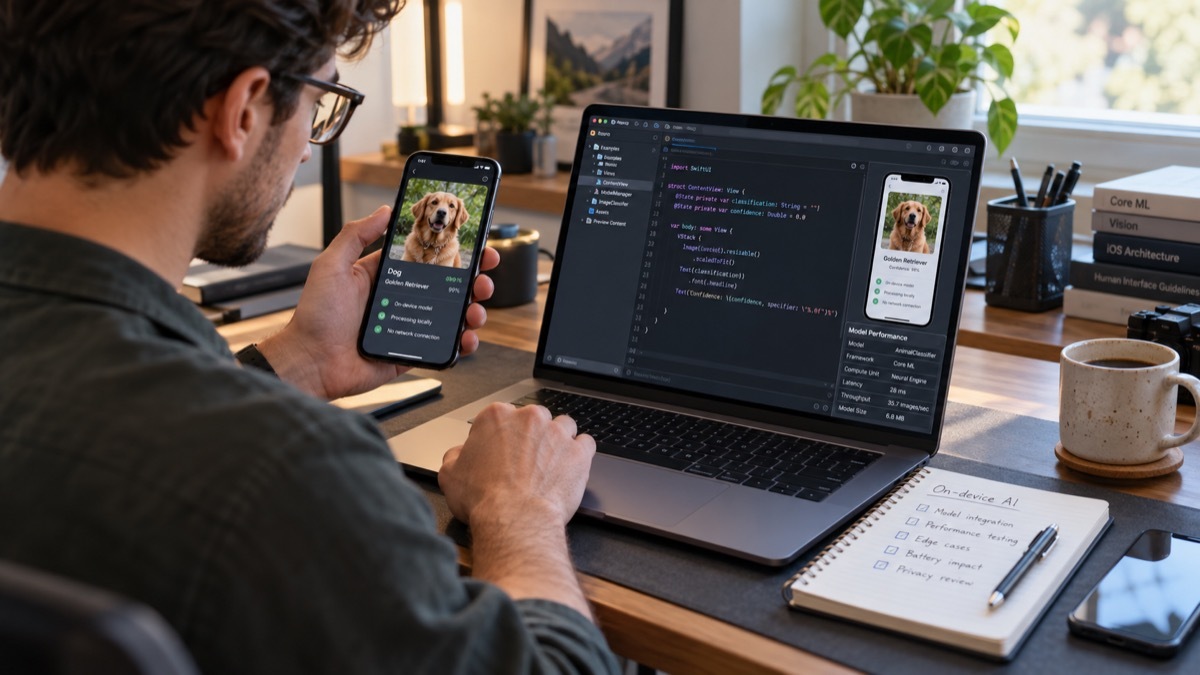
Apple’s push toward on-device inference has accelerated faster than most developers anticipated. Core ML has been capable enough for specialized tasks for several years, but the hardware generation that shipped in recent iPhone models changed the practical ceiling. Models that previously required significant cloud infrastructure can now run locally at speeds that are acceptable for real-time inference. The implications for what an iOS app can do without a network request are meaningful and still being worked out in production.
What moves on-device and what does not
The category of tasks that runs well on-device has expanded but is not unlimited. Image classification, natural language processing at moderate context lengths, voice transcription, style transfer, object detection, and semantic similarity are all practical on current iPhone hardware without perceptible latency for most use cases. Recommendations on a small local corpus, content filtering, and real-time audio processing are also viable.
What remains cloud-dependent is any task that requires a large context window, access to data that lives off-device, or inference at a scale the local model cannot cover. Large language model interaction, retrieval-augmented generation across a non-local corpus, and anything requiring server-side state stays in the cloud. The practical architecture is now hybrid rather than cloud-first, with the device handling what it can and offloading only what it must.
The privacy implications are not incidental
Apple has built its positioning around on-device processing specifically because it resolves the data transmission problem. A model that runs entirely on the device never transmits the user’s data to a server, which eliminates a category of privacy concern that regulators have been focused on for several years and that users have become more attentive to.
For developers building apps that handle sensitive data, health metrics, financial behavior, or private communications, the shift to on-device inference is not just a performance optimization. It changes the regulatory surface of the application. Data that never leaves the device does not require the same consent flows, retention policies, and breach notification procedures as data sent to a cloud endpoint. For apps in regulated verticals, this is a meaningful change in what a compliant architecture looks like.
What this requires from iOS development teams
Building an app that uses on-device inference well requires a different set of skills than building a conventional cloud-connected app. Core ML model integration, quantization decisions that balance model size against accuracy, testing across the device hardware range that the app’s users actually own, and fallback behavior for devices that cannot run the model at acceptable speeds all require experience that is specific to the platform.
This is one of the places where the gap between iOS teams that specialize in the platform and generalist shops that treat iOS as another deployment target is most visible. The tooling exists. The capability is real. But building it correctly requires engineers who have shipped this in production before and understand where the assumptions break down.
Teams evaluating what a considered iOS development approach for an on-device AI use case actually involves will find the architecture questions surface quickly. The more important question is not whether on-device inference is possible but how it integrates with the rest of the app and what happens when it does not work the way the demo suggested.
The direction of travel
On-device AI on iOS is not a niche feature set anymore. It is becoming a baseline expectation for a category of apps that need to work offline, protect user data, or respond in real time without the latency of a round trip to a server. The developers who understand how to use it well are building a meaningful capability advantage over teams that are still treating the device as a display layer.